Stanford
University
  • Stanford Home
  • Maps & Directions
  • Search Stanford
  • Emergency Info
  • Terms of Use
  • Privacy
  • Copyright
  • Trademarks
  • Non-Discrimination
  • Accessibility
© Stanford University.  Stanford, California 94305.
Uncertainty in AI | Stanford HAI
Skip to content
  • About

    • About
    • People
    • Get Involved with HAI
    • Support HAI
    • Subscribe to Email
  • Research

    • Research
    • Research Programs
    • Grants
    • Marlowe (opens in new tab)
    • Student Affinity Groups
    • Centers & Labs
    • Research Publications
    • Research Partners
  • Education

    • Education
    • Executive and Professional Education
    • Government and Policymakers
    • K-12
    • Stanford Students
  • Policy

    • Policy
    • Policy Publications
    • Policymaker Education
    • Student Opportunities
  • AI Index

    • AI Index
    • AI Index Report
    • Global Vibrancy Tool
    • People
  • News
  • Events
  • Industry
  • Centers & Labs

Stay Up To Date

Get the latest news, advances in research, policy work, and education program updates from HAI in your inbox weekly.

Sign Up For Latest News

Navigate
  • About
  • Events
  • AI Glossary
  • Careers
  • Search
Participate
  • Get Involved
  • Support HAI
  • Contact Us
Your browser does not support the video tag.
eventWorkshop

Uncertainty in AI

Status
Past
Date
Tuesday, December 10, 2019 3:00 PM - 4:00 PM PST/PDT
Topics
Machine Learning

Faculty Leaders: Elaine Treharne and Mark Algee-Hewitt


This workshop focused on “Uncertainty in AI Situations” asks researchers to consider what
an AI can do when faced with uncertainty. Machine learning algorithms whose
classifications rely on posterior probabilities of membership often present ambiguous
results, where due to unavailable training data or ambiguous cases, the likelihood of any
outcome is approximately even. In such situations, the human programmers must decide
how the machine handles ambiguity: whether making a “best-fit” classification or reporting
potential error, there is always a potential conflict between the mathematical rigor of the
model and the ambiguity of real-world use cases.

Some questions asked that begin the process of advancing AI to a new intellectual understanding of the trickiest problems in the machine-learning environment.

• How do researchers create training sets that engage with uncertainty, particularly
when deciding between reflecting real-world data and curating data sets to avoid
bias?
• How can we frame ontologies, typologies, and epistemologies that can account for,
and help solve, ambiguity in data and indecision in AI?
Share
Link copied to clipboard!

Related Events

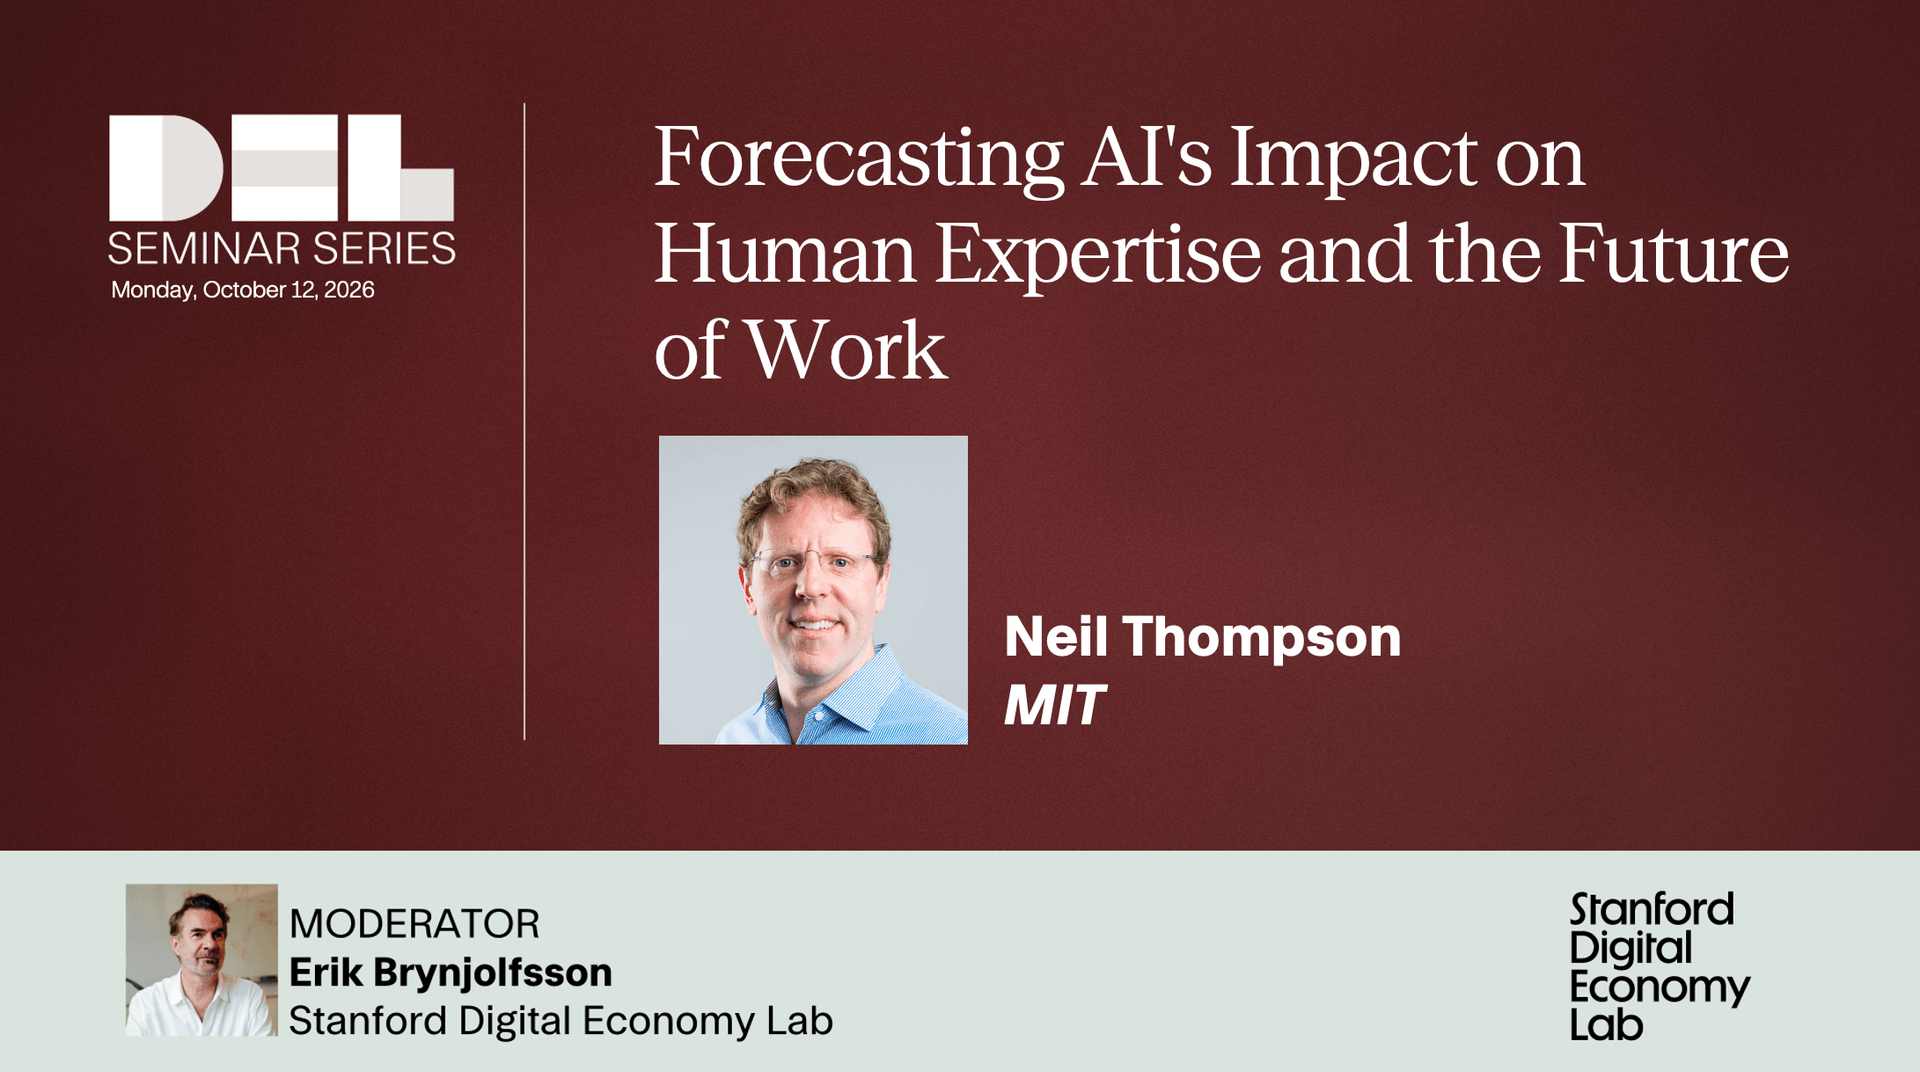
Neil Thompson: Forecasting AI’s Impact on Human Expertise and the Future of Work
Oct 12, 202612:00 PM - 1:00 PM
October
12
2026

AI is advancing rapidly at the cognitive tasks that make up knowledge work, raising fears among firms, policymakers, and, not least, workers of a “China shock” for white-collar jobs. Neil Thompson will present new research on whether those fears are warranted.

Event

Neil Thompson: Forecasting AI’s Impact on Human Expertise and the Future of Work

Oct 12, 202612:00 PM - 1:00 PM

AI is advancing rapidly at the cognitive tasks that make up knowledge work, raising fears among firms, policymakers, and, not least, workers of a “China shock” for white-collar jobs. Neil Thompson will present new research on whether those fears are warranted.

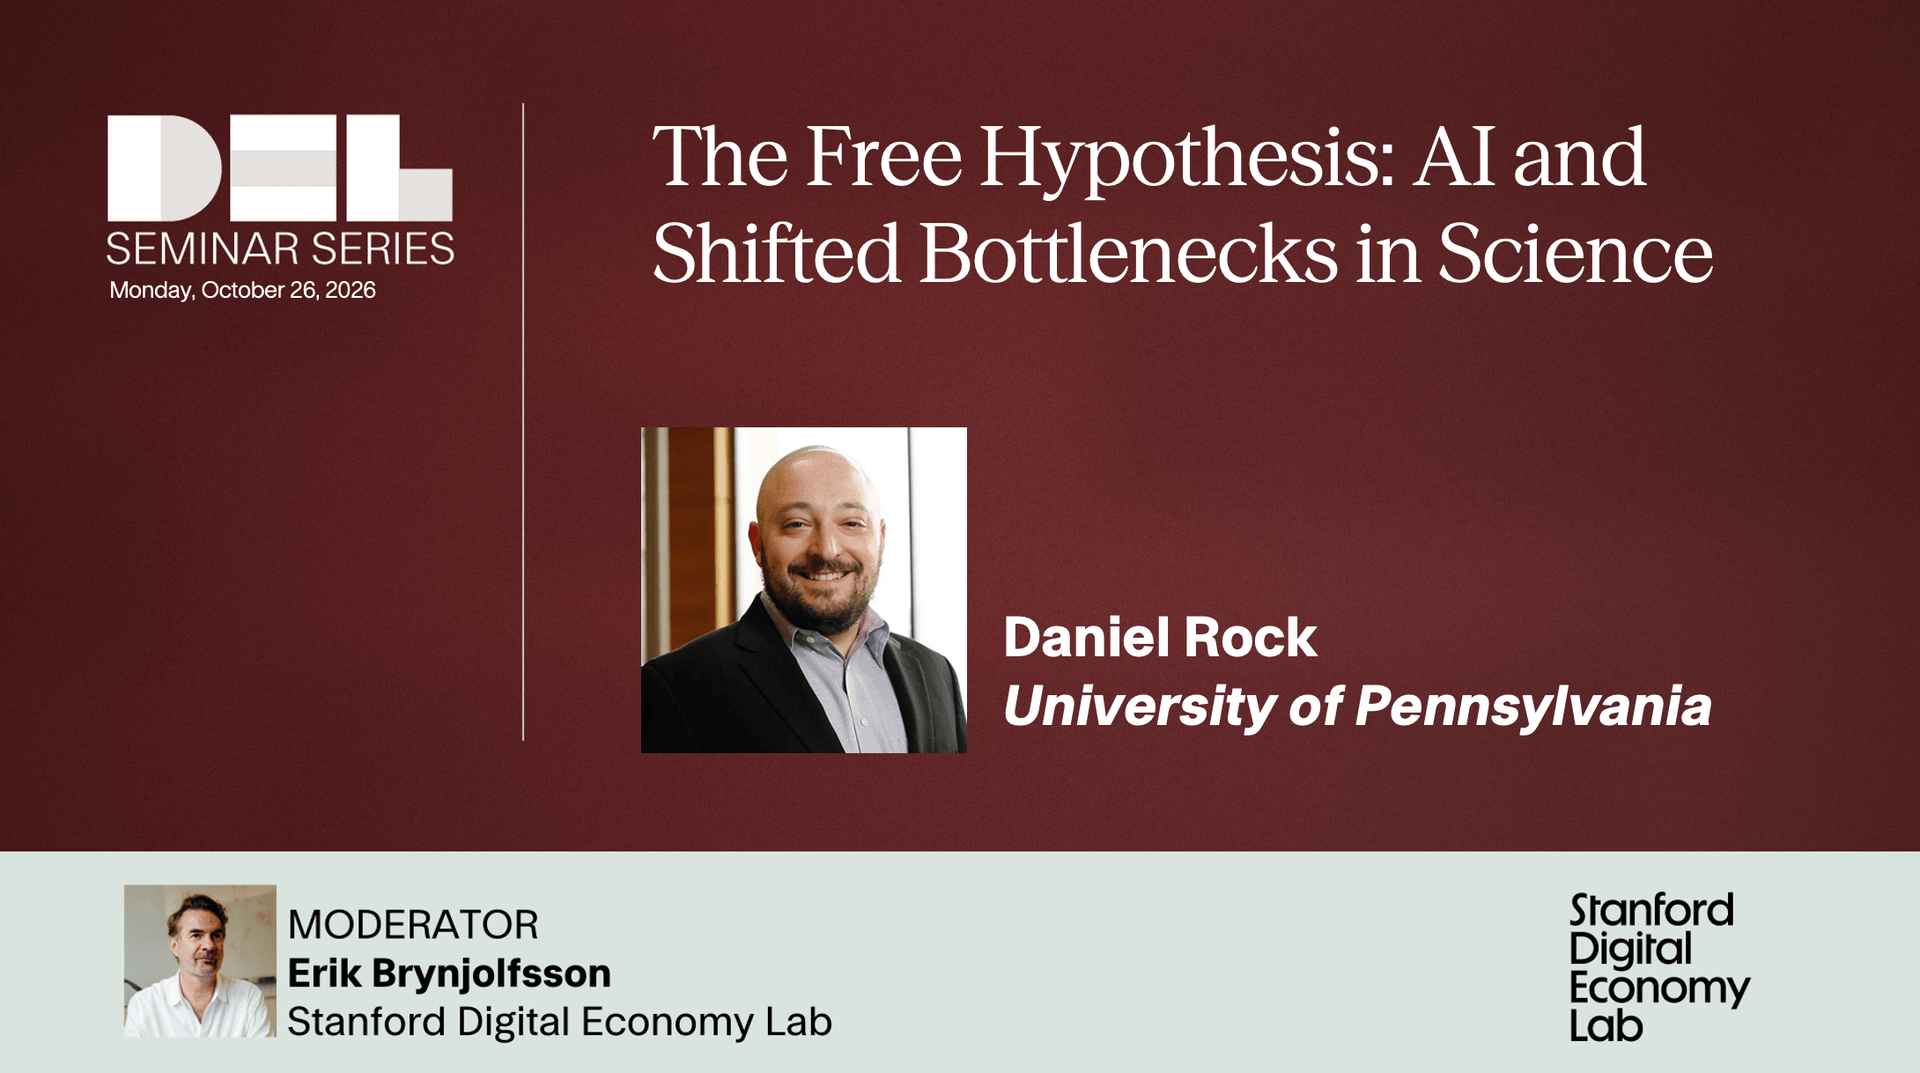
Daniel Rock | The Free Hypothesis: AI and Shifted Bottlenecks in Science
Oct 26, 202612:00 PM - 1:00 PM
October
26
2026

Scientific progress is a key driver of economic growth and prosperity. There is great excitement- but also concerns- about the impacts of AI on science, but so far little data. We provide early insights on this from three data sources: a sample of 15 million Gemini interactions, an inventory of over 2,600 specialized AI models across disciplines, and a survey of over 600 scientists.

Event

Daniel Rock | The Free Hypothesis: AI and Shifted Bottlenecks in Science

Oct 26, 202612:00 PM - 1:00 PM

Scientific progress is a key driver of economic growth and prosperity. There is great excitement- but also concerns- about the impacts of AI on science, but so far little data. We provide early insights on this from three data sources: a sample of 15 million Gemini interactions, an inventory of over 2,600 specialized AI models across disciplines, and a survey of over 600 scientists.

Tim de Silva | AI Financial Advice: Supply, Demand, and Life Cycle Implications
SeminarOct 07, 202612:00 PM - 1:15 PM
October
07
2026
Seminar

Tim de Silva | AI Financial Advice: Supply, Demand, and Life Cycle Implications

Oct 07, 202612:00 PM - 1:15 PM

This workshop focused on “Uncertainty in AI Situations” asks researchers to consider what
an AI can do when faced with uncertainty. Machine learning algorithms whose
classifications rely on posterior probabilities of membership often present ambiguous
results, where due to unavailable training data or ambiguous cases, the likelihood of any
outcome is approximately even. In such situations, the human programmers must decide
how the machine handles ambiguity: whether making a “best-fit” classification or reporting
potential error, there is always a potential conflict between the mathematical rigor of the
model and the ambiguity of real-world use cases.

Some questions asked that begin the process of advancing AI to a new intellectual understanding of the trickiest problems in the machine-learning environment.

• How do researchers create training sets that engage with uncertainty, particularly
when deciding between reflecting real-world data and curating data sets to avoid
bias?
• How can we frame ontologies, typologies, and epistemologies that can account for,
and help solve, ambiguity in data and indecision in AI?


Elaine Treharne
Roberta Bowman Denning Professor of Humanities, and by courtesy, of German Studies
Mark Algee Hewitt
Assistant Professor of English, Stanford University