eventSeminar
Khaoula Chehbouni | Best Practices for the Use of LLMs as Judges
SeminarNov 13, 20261:00 PM - 2:15 PM
November
13
2026
An AI Measurement Science (AIMS) Seminar Series
Event
An AI Measurement Science (AIMS) Seminar Series
Get the latest news, advances in research, policy work, and education program updates from HAI in your inbox weekly.
Sign Up For Latest News
An AI Measurement Science (AIMS) Seminar Series
An AI Measurement Science (AIMS) Seminar Series
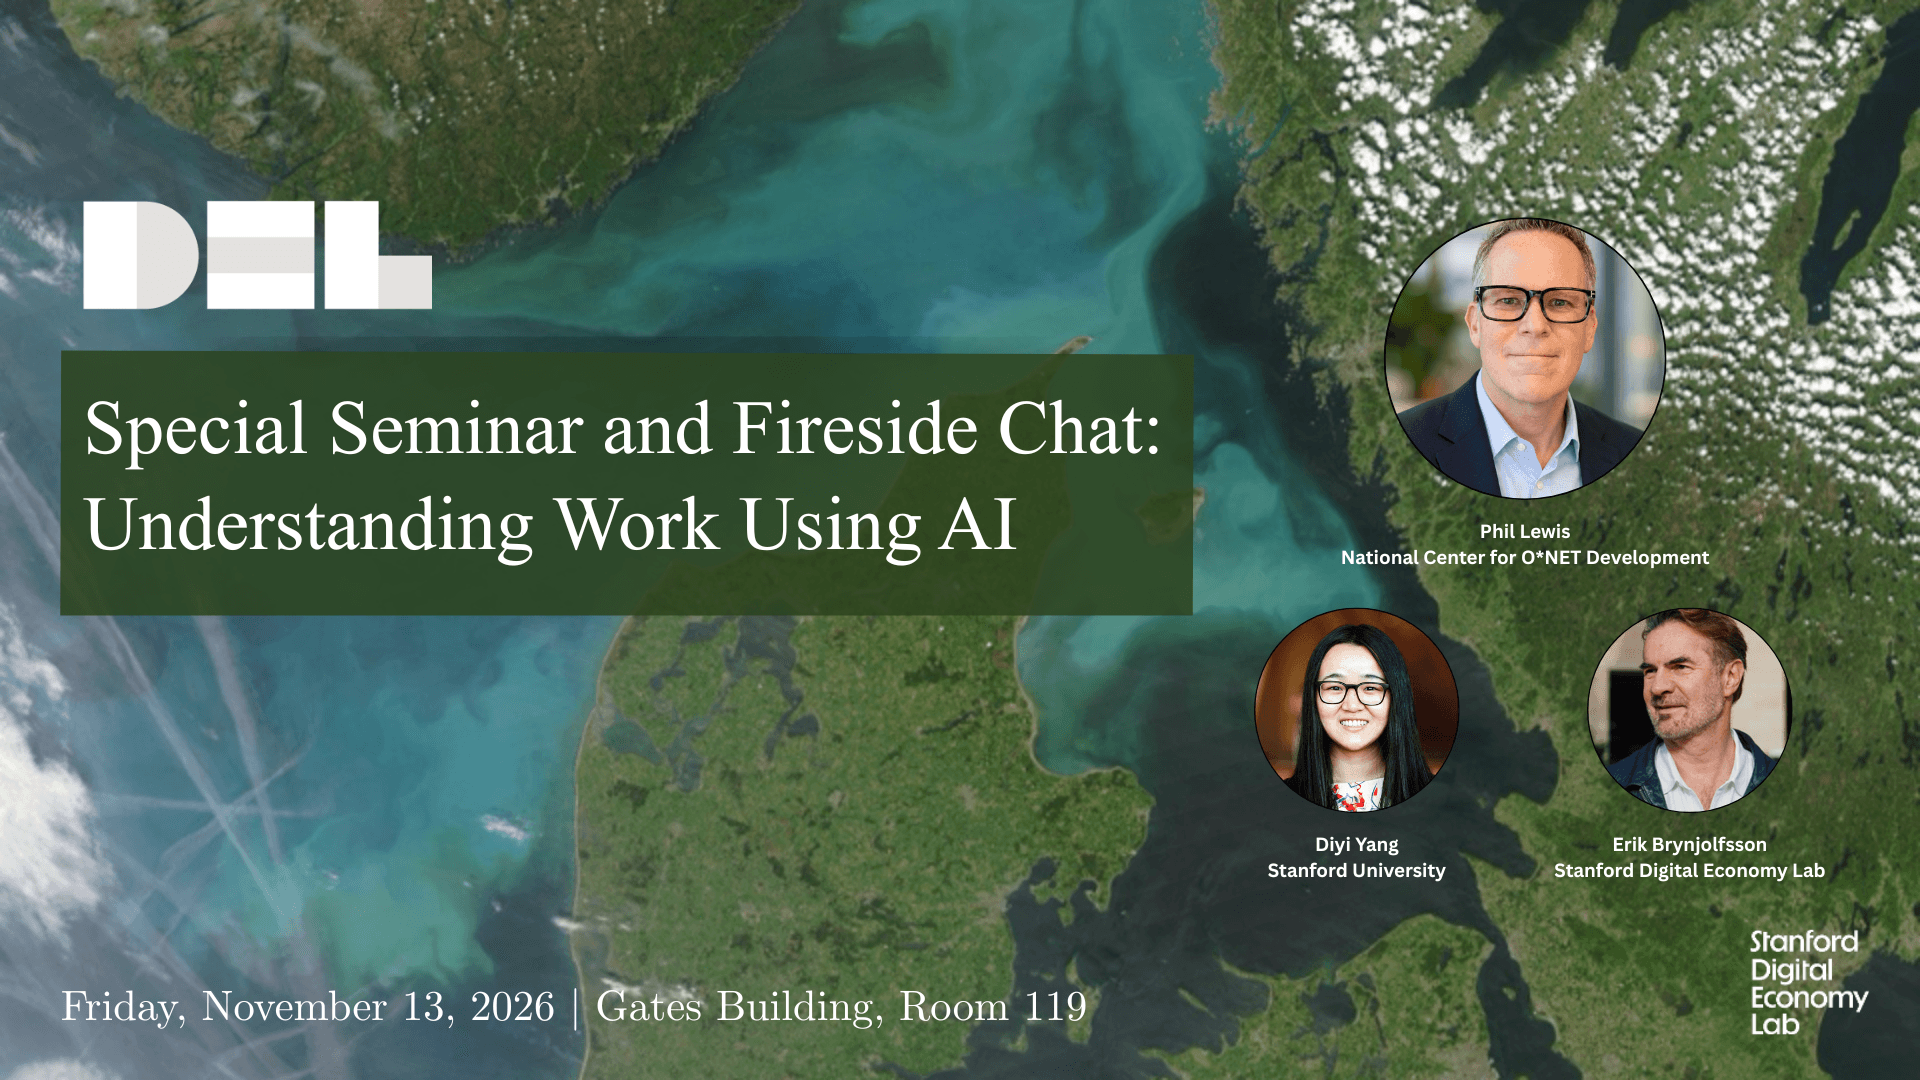
Phil Lewis from the National Center for O*NET Development will talk about data infrastructure the US Department of Labor provides, and how AI is used to update it. A panel with Diyi Yang from the Stanford Computer Science Department and DEL’s Erik Brynjolfsson will discuss the opportunities of a new partnership between Stanford and the National Center for O*NET Development.
Phil Lewis from the National Center for O*NET Development will talk about data infrastructure the US Department of Labor provides, and how AI is used to update it. A panel with Diyi Yang from the Stanford Computer Science Department and DEL’s Erik Brynjolfsson will discuss the opportunities of a new partnership between Stanford and the National Center for O*NET Development.
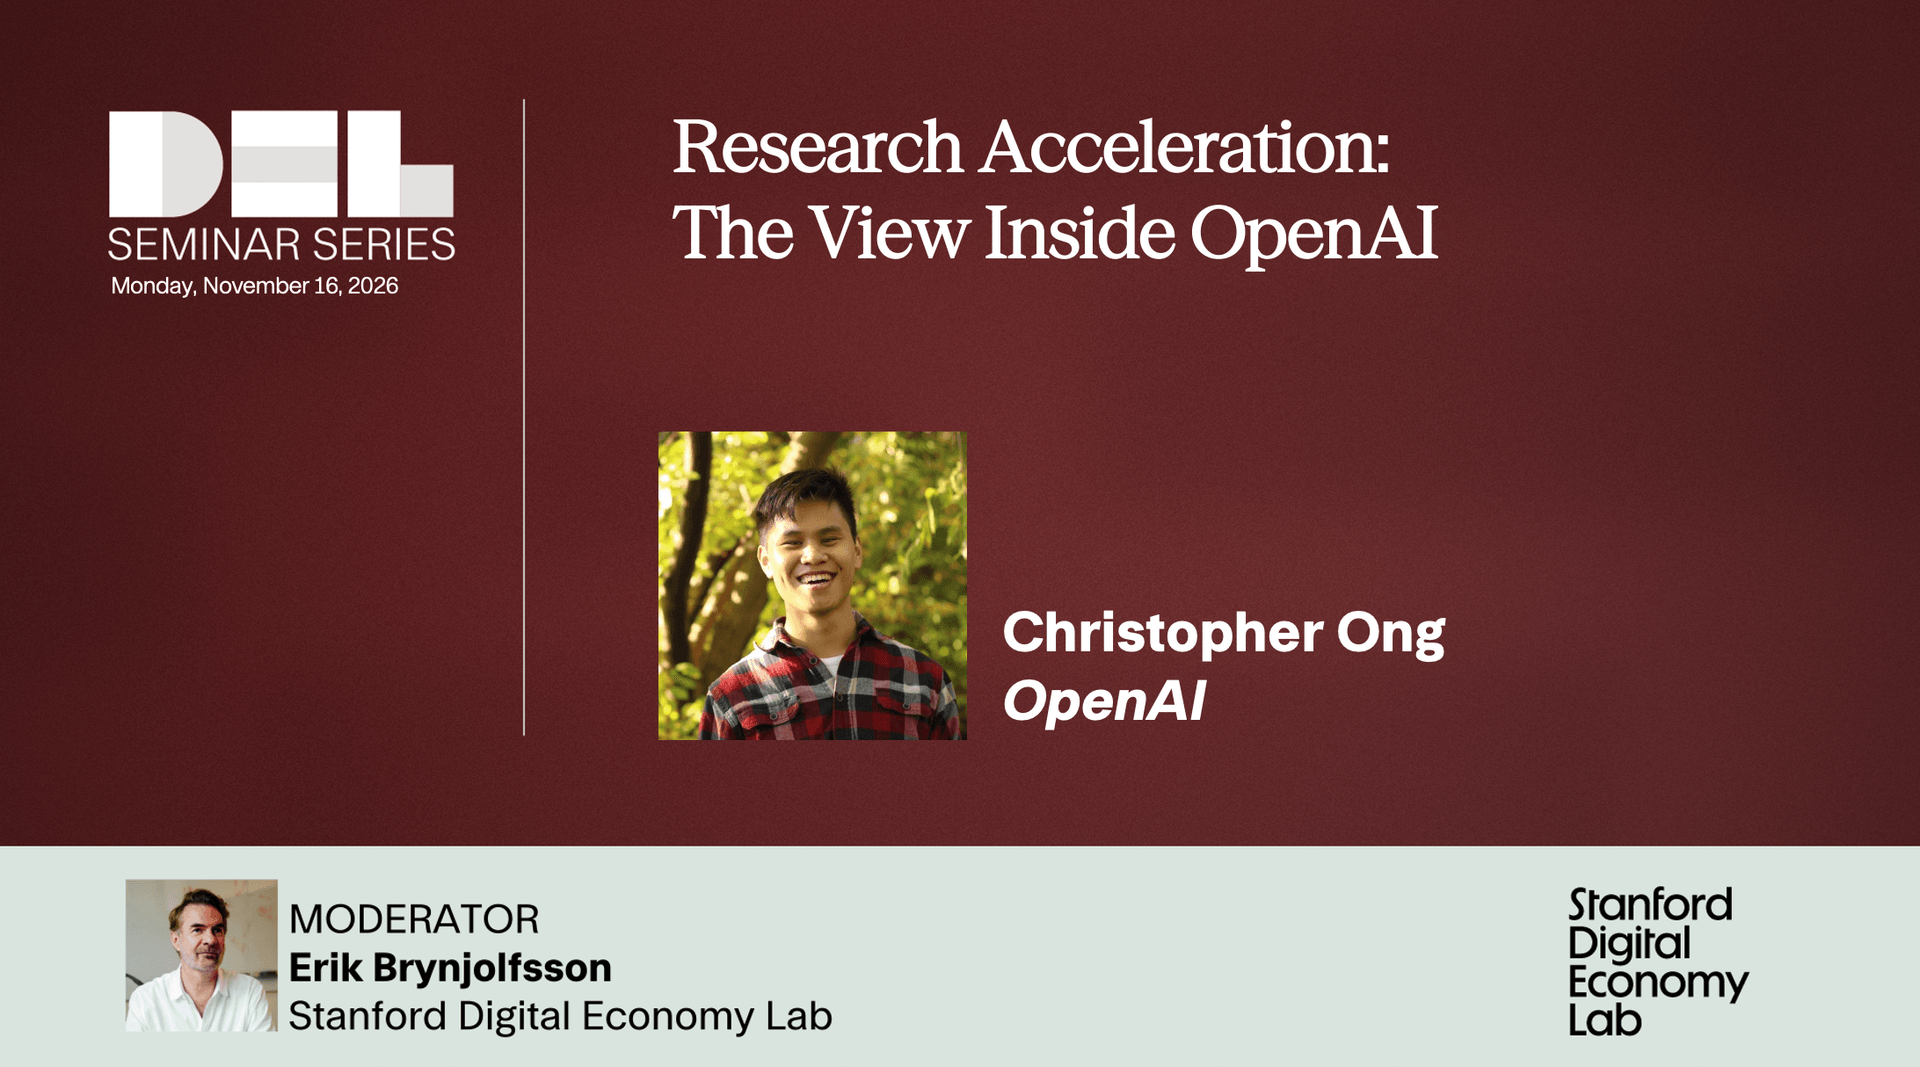
In the last year, AI models have rapidly improved on public benchmarks measuring their ability to carry out research tasks autonomously. Such performance suggests that models may be capable of automating parts of the AI R&D process itself, thereby accelerating the pace of AI progress.
In the last year, AI models have rapidly improved on public benchmarks measuring their ability to carry out research tasks autonomously. Such performance suggests that models may be capable of automating parts of the AI R&D process itself, thereby accelerating the pace of AI progress.
The stochastic multi-armed bandit (MAB) is a benchmark model for decision-making under uncertainty. In the classical MAB setting, a decision maker sequentially chooses between a set of alternatives ("arms"), and earns a reward upon each choice. The decision maker's goal is to ensure these rewards are as high as possible over their decision horizon. MABs are used in a wide range of applications, from Internet advertising to healthcare.
It is well known that high performing MAB algorithms must balance "exploration", i.e., learning about relatively unknown arms, against "exploitation", i.e., leveraging arms that have already been seen to perform reasonably well. Unfortunately, due to practical constraints, fairness requirements, and ethical considerations, actively exploring may not be possible in some domains. For example, in health care, "exploration" may involve using an untested treatment on a prospective patient, but ethical considerations may preclude such use without appropriate safeguards.
Surprisingly, a body of recent research has suggested that in many practical regimes of interest, algorithms for MAB problems that focus solely on exploitation (i.e., choosing the empirical best arm) -- known as "greedy" algorithms -- in fact can perform quite well, due to exploration that happens for "free" during the run of the algorithm. In this talk we describe this phenomenon; highlight its specific emergence in particular in MAB problems with large numbers of arms, as well as in a range of other settings; and suggest directions for future investigation.
Joint work with Nima Hamidi, Ramesh Johari, and Khashayar Khosravi.
Read "When 'Greedy' is Good" here
 Mohsen Bayati
Associate Professor of Operations, Information and Technology at The Graduate School of Business and, by courtesy, of Electrical Engineering
No tweets available.